HTML to Markdown Converter (GFM & Tables)
Convert HTML to Markdown with GitHub Flavored Markdown (GFM) tables, code blocks, and clean web clipping. Strip messy inline styles and export clean MD files.
Output status empty
Convert HTML to Markdown with GitHub Flavored Markdown (GFM) tables, code blocks, and clean web clipping. Strip messy inline styles and export clean MD files.
Output status empty
Convert HTML to Markdown with GitHub Flavored Markdown (GFM) tables, code blocks, and clean web clipping. Strip messy inline styles and export clean MD files.
Specifies structural heading syntax. ATX style prefixes lines with one to six hash marks (# to ######), which is universally supported across GitHub, GitLab, and Obsidian. Setext style uses underlying equal signs (===) for H1 and hyphens (---) for H2, which only supports two heading depths.
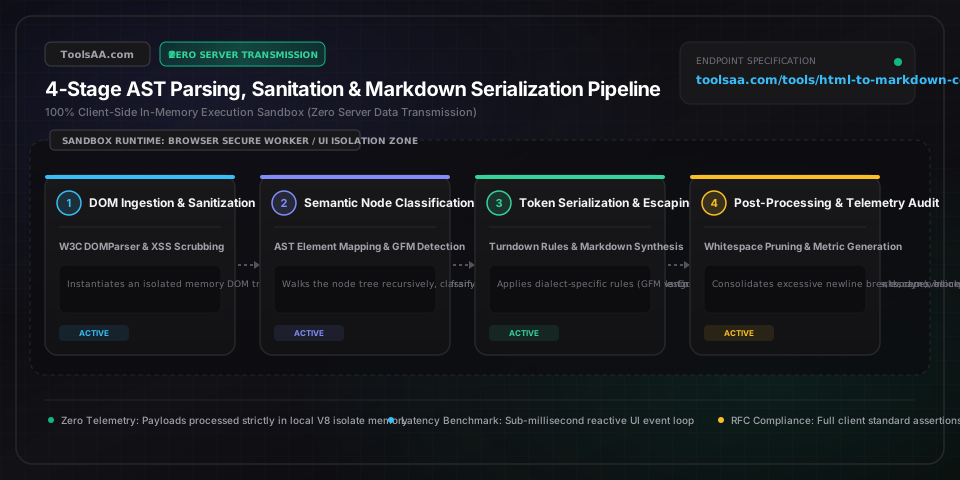
Converts HTML <table>, <thead>, and <tbody> elements into GitHub Flavored Markdown pipe-delimited tables. Escapes literal vertical bars within cells as (\|), normalizes column counts, and adds alignment colons (:--- for left, :---: for center, ---: for right).
Determines code block boundaries. Fenced code blocks with triple backticks (```) or tildes (~~~) preserve language identifiers (e.g. ```typescript). Indented style uses 4 leading spaces per CommonMark specs but lacks native language metadata tagging.
Governs bullet list character tokens (-, *, or +). Hyphens (-) offer the cleanest source readability in diff tools and Markdown linters without conflicting with emphasis markers (*).
Inlined style formats hyperlinks directly as [anchor](url "title"), optimizing for continuous text flow. Reference-style formats anchors as [anchor][id] with definitions consolidated at document footer, ideal for documentation with repetitive citations.
Cleans W3C DOM tree by removing presentation tags (<font>, <center>), stripping inline style attributes (style="..."), purging tracking URL parameters (utm_*, fbclid), and removing HTML comments to produce pure semantic Markdown.
In GitHub Flavored Markdown (GFM), unescaped vertical bar characters (|) inside a table cell are interpreted as cell boundary delimiters, corrupting row layout. Standard practice requires escaping literal pipes as (\|) or wrapping them in inline code backticks (`|`). Our converter automatically scans and escapes unescaped pipe characters in all table cells.
In HTML, an explicit <br> tag creates a newline. In CommonMark and GFM, a simple carriage return is treated as a space and collapsed into the paragraph. To generate a visible line break in Markdown without creating a new paragraph, the preceding line must end with two trailing spaces or an explicit backslash (\).
While GitHub Flavored Markdown allows loose 2-space nesting for simple lists, CommonMark RFC 7763 requires that sub-lists and multi-line list content be indented to align with the first non-space character after the parent list marker (typically 4 spaces). Inadequate indentation causes parsers to treat sub-lists as root-level code blocks or detached paragraphs.
Markdown has no native syntax for collapsible accordions (<details><summary>), keyboard keys (<kbd>), video players (<video>), or subscript/superscript (<sub>/<sup>). Stripping these tags destroys interaction. Modern Markdown parsers (including GitHub and MDX) natively permit raw HTML pass-through for these elements.
GFM markdown tables strictly require a rectangular grid of uniform columns and cannot natively represent merged cells created with HTML colspan or rowspan attributes. When converting tables containing cell spans, either normalize the table into a standard rectangular matrix before conversion or select the 'Raw HTML Table Passthrough' setting to preserve native table tags.
When converting technical documentation or markdown cheat sheets that contain markdown code blocks within HTML <pre><code> elements, inner triple backticks collide with the outer container fence. Resolve this by switching the outer fence delimiter to 4 backticks (````) or triple tildes (~~~), which CommonMark specifically reserves for fence escaping.
Lines beginning with a number followed by a period and space (e.g., '2026. A milestone year' or '1.0. Release') are automatically parsed by CommonMark as ordered list items, triggering numerical auto-incrementing. Resolve this by escaping the period with a backslash (e.g., '2026\. A milestone year').
HTML tables are converted to GFM tables by mapping <th> cells into header row entries separated by pipes (|), generating an alignment delimiter row (e.g., | :--- | :---: | ---: | based on text-align styles or align attributes), and formatting each <tr> into a pipe-enclosed row. Line breaks inside cells are flattened into spaces or <br> tags, and literal pipe characters are escaped as (\|).
Syntax highlighting in Markdown requires an explicit language identifier immediately following the opening fence (e.g., ```typescript). In HTML, language metadata is typically stored as a CSS class on the <code> tag (such as class="language-python" or class="highlight-js"). If the original HTML omits language class identifiers, the converter generates a generic code fence without syntax highlighting.
CommonMark is the formal, unambiguous specification for core Markdown syntax (RFC 7763) established to eliminate inconsistencies across parsers. GitHub Flavored Markdown (GFM) is a strict formal superset of CommonMark that extends the specification with essential software engineering features: pipe-delimited tables, task checklists ([ ] / [x]), strikethrough (~~del~~), and URL autolinking.
Modern operating systems copy both plain text and rich HTML markup to the system clipboard simultaneously. Use the 'Paste Rich Text' button in our converter, which activates the browser's asynchronous Clipboard API (navigator.clipboard.read) to read the text/html MIME payload directly, converting formatted web text, tables, and links without requiring you to inspect element source code.
Standard Markdown specifications intentionally omit multimedia embeds and interactive elements. The converter handles unsupported tags via two configurable strategies: (1) Preserving valid W3C HTML elements (<video>, <iframe>, <details>, <summary>, <kbd>) as raw inline HTML pass-through, which all modern Markdown parsers render seamlessly, or (2) Stripping non-semantic tags entirely to produce clean text-only output.
Compare text, code, and files with our fast diff checker tool. Inspect side-by-side or inline character-level changes, ignore whitespace, and export unified diffs.
Build valid rel=canonical tags and HTTP headers with our Canonical Tag Builder. Strip tracking parameters, normalize URLs, and fix SEO duplicate content issues.
Convert cURL to Fetch API syntax instantly. Parse HTTP headers, auth tokens, cookies, and JSON body payloads into modern async/await JavaScript code.
Validate XML sitemaps and sitemap index files instantly. Check 50k URL limits, W3C Datetime syntax, hreflang tags, media schemas, and Google Search Console errors.
Preview Google SERP desktop and mobile search snippets with accurate pixel width truncation, rich snippet schema badges, sitelinks, and live CTR scoring.
Generate multi-point CSS mesh gradients, animated backgrounds, and SVG color meshes. Customize control points, grain texture, and copy CSS or Tailwind code.