Regex Tester & Regular Expression Debugger

Regex Tester & Regular Expression DebuggerBadge version

Test, debug, and optimize regular expressions in real time. Inspect regex pattern matches, capture groups, step-by-step token explanations, and replace syntax.

Lbl engine flavor
Lbl line endings
Lbl quick presets
Title regex workbench
//gm
Lbl quick palette
Reach out to [email protected]#1 or [email protected]#2 for inquiries. Invalid addresses like john..doe@bad#3_domain or @missing-user.org should be ignored. Admin contact: [email protected]#4.
Lbl match details listLbl matches total: 4
Lbl match word #1: "[email protected]"Lbl pos: [13:32] (19 Unit chars)
<user>: "support"<domain>: "toolsaa.com"
Lbl match word #2: "[email protected]"Lbl pos: [36:66] (30 Unit chars)
<user>: "sales.dept"<domain>: "enterprise-cloud.io"
Lbl match word #3: "john..doe@bad"Lbl pos: [105:118] (13 Unit chars)
<user>: "john..doe"<domain>: "bad"
Lbl match word #4: "[email protected]"Lbl pos: [181:212] (31 Unit chars)
<user>: "sec-ops"<domain>: "datacenter.internal.net"
Stat matches
4
Stat capture groups
2 Unit groups
Stat re do s status
Stat protected

Client-Side Processing

High-performance calculation executed entirely in browser memory.

Zero Server Upload Privacy

All payloads remain strictly local with zero external server communication.

Production Ready Export

Clean, optimized output formats ready for immediate deployment.
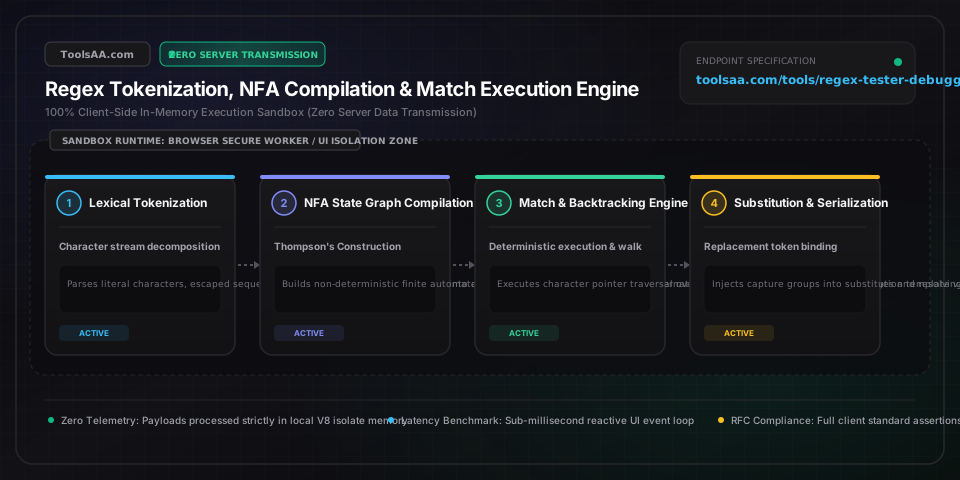
Technical Reference & Architecture Guide

Regex Tester & Regular Expression Debugger Guide

Test, debug, and optimize regular expressions in real time. Inspect regex pattern matches, capture groups, step-by-step token explanations, and replace syntax.

Regex Tester & Regular Expression Debugger Guide — Client-Side In-Memory Architecture & Data Flow

Key Parameters & Controls

Regular Expression PatternRegExp Syntax String

Standard regular expression literal containing character classes, anchors, quantifiers, and capturing groups conforming to ECMAScript RegExp specifications.

Default: /(?<user>[a-zA-Z0-9._%+-]+)@(?<domain>[a-zA-Z0-9.-]+\.[a-zA-Z]{2,})/gm
Regex Execution FlagsBitmask Flag String

Active compilation modifiers modifying regex runtime behavior: g (global search), i (case insensitive), m (multiline anchors ^ and $), s (dotAll mode where dot matches newline), u (unicode code point support), y (sticky matching at lastIndex).

Default: gm
Test Corpus Target TextRaw String Corpus

The multiline input document against which the regular expression is executed to find occurrences, evaluate group captures, and test performance.

Default: sample text corpus
Substitution Template PatternReplacement String

Template pattern for string replacement supporting positional backreferences ($1, $2), named capture group identifiers ($<name>), complete match text ($&), and prefix/suffix slices ($`, $').

Default: $<user> at $<domain>

Pro Tips & Best Practices

Prevent Catastrophic Backtracking (ReDoS) with Mutually Exclusive Tokens

Nested unbounded quantifiers such as (a+)+ or (.*a)+ cause Non-deterministic Finite Automaton (NFA) engines to explore O(2^n) states when matching failing inputs. Eliminate overlapping character classes inside repetitions and prefer atomic grouping, possessive quantifiers, or strictly negated character sets like [^a]*a.

Beware the Stateful lastIndex Property with Global (g) and Sticky (y) Flags

When a RegExp instance has the /g or /y flag enabled, the native JavaScript engine maintains an internal lastIndex pointer that advances after each match. Calling regex.test() repeatedly on the same string will alternate between returning true and false unless you explicitly reset regex.lastIndex = 0 before execution.

Enforce the Unicode Flag (u or v) for Multibyte Astral Plane Characters and Emojis

Standard JavaScript regex without the /u flag treats 4-byte UTF-16 surrogate pairs as two separate 2-byte code units. A dot (.) will fail to match a single emoji like 🚀 (\uD83D\uDE80) as one character unless /u or /v is enabled, and character range classes [\u{1F600}-\u{1F64F}] will throw syntax errors.

Distinguish Multiline Flag (m) from DotAll Flag (s) in Line-Break Handling

The /m flag only redefines the anchors ^ and $ to match the beginning and end of each individual line within a multiline string instead of just the whole document. It does NOT allow the dot wildcard (.) to match line feeds (\n) or carriage returns (\r); for dot to span across line boundaries, you must explicitly enable the /s (dotAll) flag.

Common Gotchas & Troubleshooting

⚠️Inadvertent Greedy Quantifier Trapping Swallowing Multiple XML/HTML Blocks

Standard quantifiers (*, +, {n,}) are greedy by default and consume as much text as possible. To stop at the earliest delimiter, append a question mark to create a lazy quantifier (e.g. change <div.*> to <div.*?>) or use a negated character class (e.g. <[^>]*>).

⚠️Unescaped Forward Slash Delimiters or Reserved Meta-Characters Causing Runtime Syntax Errors

Characters with special syntactic meaning in regex (\, ^, $, ., |, ?, *, +, (, ), [, ], {, }) must be escaped with a preceding backslash when matched as literal characters. When constructing patterns dynamically from strings via new RegExp(), remember that double-escaping (\\) is required in source code.

⚠️Negative Lookahead (?!pattern) Confused with Negated Character Class [^chars]

A negated character class [^abc] consumes exactly one character that is not 'a', 'b', or 'c'. A negative lookahead assertion (?!abc) is a zero-width assertion that checks whether the subsequent multi-character sequence is not 'abc' without consuming any characters.

Frequently Asked Questions

How to test regex without catastrophic backtracking ReDoS vulnerability?▼

Catastrophic backtracking occurs when an NFA regex engine encounters nested quantifiers with overlapping sub-patterns (such as (a+)+$ or (x|y+)*) matching a non-matching string, leading to O(2^n) exponential computational complexity. To prevent this, ensure repeated groups are mutually exclusive, replace greedy wildcards like .* with strict negated classes like [^\n,]+, and benchmark execution time against failing test inputs.

What is the difference between regex greedy lazy and possessive quantifiers?▼

Greedy quantifiers (*, +, {min,max}) consume as much text as possible and backtrack one step at a time if the overall pattern fails. Lazy quantifiers (*?, +?, {min,max}?) consume as little text as possible, expanding one character at a time as needed. Possessive quantifiers (*+, ++, {min,max}+), supported in PCRE and Java, consume all matching characters greedily and never backtrack, failing immediately if downstream tokens do not match.

Why does regex test return true then false on identical strings?▼

When a regular expression is compiled with the global (/g) or sticky (/y) flag in JavaScript, the RegExp object preserves state by updating its internal lastIndex property to the character index immediately following the last successful match. If invoked a second time, searching starts from lastIndex rather than index 0; once it reaches the end of the string, it resets to 0 and returns false. Reset regexObject.lastIndex = 0 before subsequent executions.

How to match across multiple lines including line breaks in regex?▼

To match across line breaks, enable the dotAll flag (/s), which configures the wildcard dot (.) to match newline characters (\n, \r) in ECMAScript 2018+, Python, and modern regex engines. In environments lacking /s support, use the complementary character set [\s\S] or [\d\D], which matches any character that is either whitespace or non-whitespace, effectively spanning all newlines.

What is the difference between capturing groups and non-capturing groups?▼

Capturing groups defined as (pattern) remember the matched sub-string in memory, assign it a numbered backreference index ($1, $2, ...), and make it accessible in match result arrays. Non-capturing groups defined as (?:pattern) apply grouping logic, quantifiers, or alternations without allocating memory overhead or populating match result arrays, improving parsing performance.

Related Tools & Utilities

All Tools →