Chi-Square Calculator & P-Value Solver

Chi-Square Calculator & P-Value Solver

Calculate chi-square test statistic, p-value, expected frequencies, and Cramér's V from 2x2 to 10x10 contingency tables or goodness-of-fit data instantly.

Lbl quick presets
Lbl significance alpha
Title contingency matrix
Lbl rows
2
Lbl cols
2
Tbl header row labelsTbl header total
1000
1000
Tbl header total28517152000
Lbl total sample2000
Badge cochran ok
Title reverse solver
Badge reverse engine

Desc reverse solver

Lbl simulated multiplier1.0x
0.2x1.0x (Lbl current scale)5.0x
Lbl projected chi28.29
Lbl projected p val0.0040
Lbl samples needed 0.05:928 Unit participantsHint at current proportions
Lbl samples for80 power1846 Unit participantsHint power benchmark
Lbl cohen w0.064(Effect size negligible)
Lbl estimated power82.1%
Lbl chi square stat8.2860Lbl critical threshold 3.841
Lbl p value0.0040Lbl threshold 0.05
Lbl degrees freedom1(r-1)×(c-1)
Lbl cramers v0.0644Interp small
Verdict significant title
Verdict significant desc
Title distribution curve
Legend rejectionLegend observed
χ²_crit = 3.84χ² = 8.290471114
Title residual heatmap
Lbl odds ratio0.690Lbl confidence interval: [0.54 - 0.89]
Lbl relative risk0.727Lbl confidence interval: [0.58 - 0.90]
Lbl arr4.5%Lbl nnt: ~22
Lbl fisher exact0.0048Hint fisher exact
Tbl header cell cohortConvertedBounced
Control Page (A)
Lbl observed short:120
Lbl expected short:142.5
Lbl z score short:-2.88
Lbl contribution short:43%
Lbl observed short:880
Lbl expected short:857.5
Lbl z score short:2.88
Lbl contribution short:7%
Variant Page (B)
Lbl observed short:165
Lbl expected short:142.5
Lbl z score short:2.88
Lbl contribution short:43%
Lbl observed short:835
Lbl expected short:857.5
Lbl z score short:-2.88
Lbl contribution short:7%
Legend over expectedLegend under expectedLegend neutral
Stat card1 title

Stat card1 desc

Stat card2 title

Stat card2 desc met

Stat card3 title

Stat card3 desc

Disclaimer title

Disclaimer text

Client-Side Processing

High-performance calculation executed entirely in browser memory.

Zero Server Upload Privacy

All payloads remain strictly local with zero external server communication.

Production Ready Export

Clean, optimized output formats ready for immediate deployment.
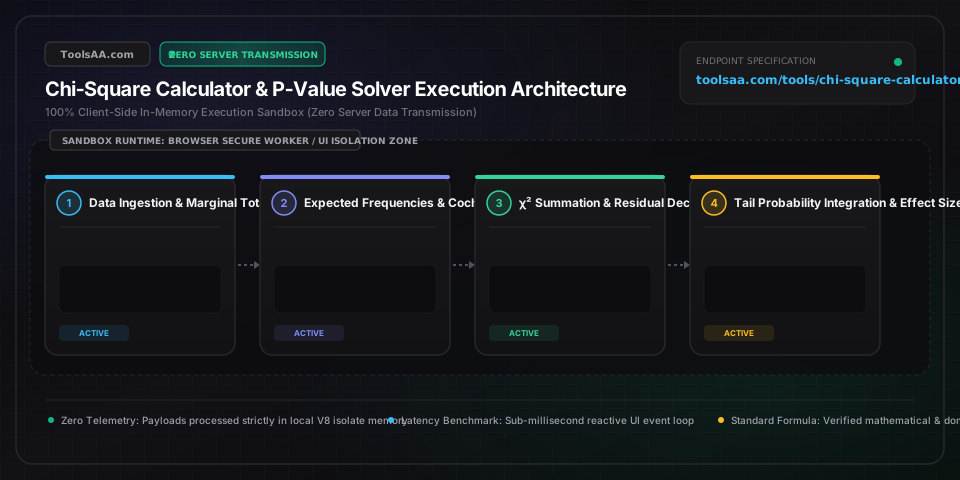
Technical Reference & Architecture Guide

Chi-Square Calculator & P-Value Solver Guide

Calculate chi-square test statistic, p-value, expected frequencies, and Cramér's V from 2x2 to 10x10 contingency tables or goodness-of-fit data instantly.

Chi-Square Calculator & P-Value Solver Guide — Client-Side In-Memory Architecture & Data Flow

Key Parameters & Controls

Observed Cell Frequencies (O_ij)Raw Frequency Counts (Integers ≥ 0)

Empirical event counts tallied across categories. To preserve statistical validity, entries must be unweighted positive integers or zero; entering percentages, ratios, or sample averages will artificially distort the test statistic and invalidate standard error calculations.

Default: Non-negative whole counts (e.g., 25, 40)
Significance Level (Alpha, α)Decision Threshold Probability (0 to 1)

The predetermined false-alarm tolerance for rejecting the null hypothesis of independence. The conventional scientific benchmark is α = 0.05 (5% risk of false alarm), while high-stakes medical and clinical trials demand α = 0.01 (1% risk) and exploratory screening often sets α = 0.10.

Default: 0.05
Degrees of Freedom (df)Independent Variance Dimensions (Positive Integer)

The number of cell frequencies free to vary while keeping fixed row and column marginal totals. Calculated as (r - 1) × (c - 1) for an r × c contingency table, or (k - 1) for a 1 × k goodness-of-fit test. Higher degrees of freedom shift the critical chi-square value threshold higher.

Default: (r - 1) × (c - 1)
Expected Cell Frequencies (E_ij)Theoretical Reference Counts (Real Numbers > 0)

Theoretical frequencies calculated under the assumption of complete statistical independence: E_ij = (Row Total × Column Total) / Grand Sample Size (N). Cochran's criterion dictates that at least 80% of cells must have E_ij ≥ 5 and no cell may have E_ij < 1.

Default: ≥ 5 per Cochran's Rule

Pro Tips & Best Practices

Preventing False Alarms in Massive Datasets (N > 10,000)

Chi-square p-values shrink toward zero as sample size balloons; with over 10,000 subjects, even a meaningless 0.2% preference difference achieves p < 0.001. Always evaluate Cramér's V alongside the p-value: a V under 0.10 confirms negligible real-world relationship despite overwhelming nominal statistical significance.

The Raw Counts Rule: Never Enter Percentages or Proportions

Entering rounded percentages (like 45% and 55%) instead of exact event tallies completely collapses the denominator of the chi-square equation. The test statistic is scale-dependent on total sample size N; substituting percentages as counts deflates N to 100, manufacturing false non-significant results when thousands of people were actually surveyed.

Isolating Specific Outliers with Adjusted Residuals

An omnibus significant p-value (p < 0.05) only confirms that a table is not independent; it does not tell you which category caused the divergence. Inspect Haberman's adjusted standardized residuals (z_adj): any cell with |z| > 1.96 (or |z| > 2.58 for α = 0.01) represents a statistically significant surplus or deficit driving your entire result.

When to Bypass Pearson for Fisher's Exact Test

In 2x2 grids where total sample size N < 40 or any expected frequency drops below 5, Pearson's chi-square and Yates' correction both lose mathematical fidelity. Use Fisher's exact test instead, which calculates exact hypergeometric combinatorics without relying on continuous curve approximations.

Common Gotchas & Troubleshooting

⚠️Cochran's Criterion Violation Warning: More than 20% of expected cell frequencies are below 5

Small expected frequencies inflate the chi-square statistic, generating spurious significance. For 2x2 contingency tables, evaluate Fisher's exact test directly. For multi-row or multi-column grids (3x3, 4x4), collapse logically contiguous or clinically similar categories (such as grouping 'rarely' and 'never') to pool counts and satisfy E_ij ≥ 5 across at least 80% of cells.

⚠️Division by Zero or Undefined Test Statistic: Marginal row or column total is zero

A row or column where every single cell is zero creates a marginal sum of zero, making expected frequencies E_ij = 0 and triggering mathematical division by zero. Remove the entirely empty category row or column from the contingency grid, or verify that observational data was entered accurately.

⚠️Significant Discrepancy Between Standard Pearson χ² and Yates' Corrected p-Value

Yates' continuity correction subtracts 0.5 from each absolute deviation (|O - E| - 0.5) to bridge discrete counts with the continuous chi-square curve in 2x2 tables. This intentionally reduces χ² and yields a larger, more conservative p-value. For small samples (N < 100), trust Yates or Fisher's exact test; for large clinical registries (N > 200), uncorrected Pearson χ² is standard practice.

Frequently Asked Questions

How do you calculate the chi-square test statistic and p-value from a contingency table?▼

To calculate the chi-square statistic: 1) Sum the observed counts along each row and column to find marginal totals and total sample size N; 2) Calculate expected frequency for each cell via E_ij = (Row Total × Column Total) / N; 3) Compute (O_ij - E_ij)² / E_ij for every cell and sum them to obtain χ²; 4) Determine degrees of freedom df = (rows - 1) × (columns - 1); 5) Integrate the upper-tail survival function of the chi-square distribution: p = P(X² ≥ χ² | df). If p ≤ 0.05, the variables demonstrate a statistically significant association.

What is a good Cramér's V benchmark for measuring practical effect size?▼

A good Cramér's V benchmark depends on degrees of freedom df* = min(r - 1, c - 1). For standard 2x2 tables (df* = 1), V = 0.10 indicates a small association, V = 0.30 represents a moderate relationship, and V ≥ 0.50 signifies a strong practical effect. In larger grids with df* = 2 (e.g., 3x3 tables), thresholds scale down to 0.07 (small), 0.21 (medium), and 0.35 (large), because spreading variance across more categories naturally lowers index magnitude.

What is the difference between a chi-square test of independence and a goodness-of-fit test?▼

A chi-square test of independence evaluates bivariate data across a two-dimensional grid (r × c) to determine if two categorical variables influence one another, using df = (r - 1) × (c - 1). In contrast, a chi-square goodness-of-fit test analyzes a single univariate variable across k categories (1 × k) to verify whether observed counts conform to an expected theoretical distribution (such as an even distribution across days of the week or Mendelian genetic ratios), using df = k - 1.

When should Yates' continuity correction be applied to a 2x2 contingency table?▼

Yates' continuity correction should be applied to 2x2 tables with moderate sample sizes (between 40 and 200) where discrete binomial counts are approximated by the continuous chi-square curve. By subtracting 0.5 from |O - E|, Yates prevents overestimating statistical significance (Type I error). However, for very small samples (N < 40 or E_ij < 5), Fisher's exact test is preferred, while for large studies (N > 200), Yates overcorrects and is unnecessary.

What should you do when expected cell frequencies fall below 5?▼

When more than 20% of contingency table cells have expected counts below 5 (violating Cochran's criterion), standard asymptotic chi-square approximations fail. For 2x2 tables, switch immediately to Fisher's exact test, which computes exact hypergeometric probabilities. For larger multi-row tables (e.g., 3x4), merge or collapse adjacent, conceptually related categories (such as combining 'strongly disagree' with 'disagree') to pool sparse cell counts above the threshold of 5.

How do adjusted standardized residuals identify which cells drive chi-square significance?▼

Adjusted standardized residuals (Haberman's z-score) isolate which specific categories produce a significant omnibus chi-square result by dividing (O_ij - E_ij) by its true asymptotic standard error: z = (O_ij - E_ij) / √[E_ij(1 - R_i/N)(1 - C_j/N)]. Because Haberman's z follows a standard normal N(0,1) distribution, any cell with |z| > 1.96 reflects statistically significant deviation at α = 0.05, and |z| > 2.58 reflects significance at α = 0.01.

Related Tools & Utilities

All Tools →