/
PostgreSQL Memory Calculator & PGTune Config
Badge tierBadge pg version

PostgreSQL Memory Calculator & PGTune Config

Calculate PostgreSQL memory settings & generate PGTune postgresql.conf parameters. Optimize shared_buffers, work_mem, effective_cache_size, and max_connections.

Lbl quick presets:

Title hardware specs

Hint platform regime

Unit gb
Tick1 gbTick16 gbTick64 gbTick128 gbTick256 gb

Hint cpu cores

Hint storage type

Unit conns
Status disabled
Lbl active backend conns100
Lbl base thread overhead1000MB
Lbl huge pages req4108
Lbl conf subtitlePostgreSQL 16 • NVMe SSD
# ----------------------------------------------------------------------
# PostgreSQL PostgreSQL 16 Performance Tuning Profile
# Generated by ToolsAA PostgreSQL Memory Calculator & PGTune Engine
# Host RAM: 32 GB | Cores: 8 | Storage: NVMe SSD
# Platform Regime: Linux Bare-Metal / VM | Workload: Web Application / High-Concurrency OLTP
# ----------------------------------------------------------------------

# ----------------------------
# Connectivity & Concurrency
# ----------------------------
max_connections = 100 # Active backend workers
superuser_reserved_connections = 3

# ----------------------------
# Memory & Cache Allocation
# ----------------------------
shared_buffers = 8GB # Hot page buffer pool
effective_cache_size = 24GB # Planner RAM estimate (Shared + OS Cache)
maintenance_work_mem = 1.6GB # Dedicated VACUUM & CREATE INDEX memory
work_mem = 98MB # Per sort/hash node memory
autovacuum_work_mem = -1 # Inherits maintenance_work_mem
huge_pages = try # Requires vm.nr_hugepages in /etc/sysctl.conf
temp_buffers = 16MB # Session-local temporary table memory

# ----------------------------
# Storage I/O & Query Planner
# ----------------------------
random_page_cost = 1.1 # Calibrated for NVMe SSD
seq_page_cost = 1.0 # Sequential disk block scan baseline
effective_io_concurrency = 300 # Prefetch asynchronous disk queues
default_statistics_target = 100 # Planner table sample resolution

# ----------------------------
# Checkpoints & WAL Journaling
# ----------------------------
checkpoint_completion_target = 0.9 # Spread checkpoint I/O over interval
checkpoint_timeout = 15min # Maximum duration between automatic checkpoints
min_wal_size = 4GB # Baseline recycled WAL buffer ring
max_wal_size = 32GB # Soft WAL ceiling before forced checkpoint
wal_buffers = 16MB # Ring buffer for unsaved WAL transactions
wal_compression = on # Lz4 or pglz compression to reduce disk I/O write amplification

# ----------------------------
# Parallel Query Execution
# ----------------------------
max_worker_processes = 8 # Maximum background and parallel workers
max_parallel_workers = 8 # Pool dedicated to parallel executor
max_parallel_workers_per_gather = 2 # Workers per single query plan node
max_parallel_maintenance_workers = 2 # Parallel index creation & VACUUM

# ----------------------------
# PostgreSQL Version-Specific Nuances
# ----------------------------
io_combine_limit = 256kB # PG16+ vectorized disk block read
track_io_timing = on # Monitor block read/write latencies
compute_query_id = on # Built-in query fingerprints for pg_stat_statements
shared_preload_libraries = 'pg_stat_statements' # Core query performance telemetry
Lbl planner status
Lbl peak ram label32.9GB
Stat shared buffers8GBStat shared buffers sub
Stat work mem98MBStat work mem sub
Stat oom risk103% PeakStat risk critical

Client-Side Processing

High-performance calculation executed entirely in browser memory.

Zero Server Upload Privacy

All payloads remain strictly local with zero external server communication.

Production Ready Export

Clean, optimized output formats ready for immediate deployment.

Disclaimer text
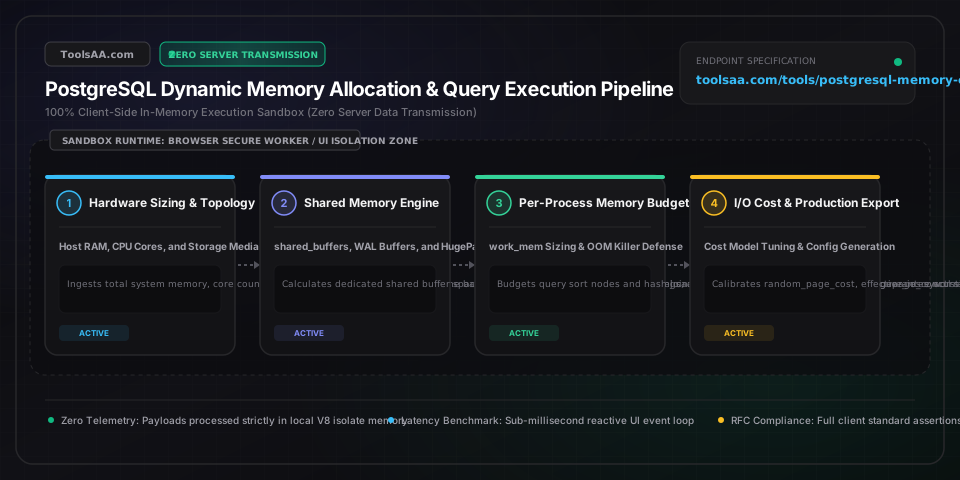
Technical Reference & Architecture Guide

PostgreSQL Memory Calculator & PGTune Config Guide

Calculate PostgreSQL memory settings & generate PGTune postgresql.conf parameters. Optimize shared_buffers, work_mem, effective_cache_size, and max_connections.

PostgreSQL Memory Calculator & PGTune Config Guide — Client-Side In-Memory Architecture & Data Flow

Key Parameters & Controls

shared_buffersMemory String (e.g., 8GB, 16GB)

Sets the dedicated memory PostgreSQL uses for shared data cache. Benchmark golden ratio is 25% of total system RAM on Linux. Setting this beyond 40% degrades performance due to double-buffering against the Linux OS page cache.

Default: 128MB (PostgreSQL Default factory setting)
work_memMemory String (e.g., 32MB, 64MB)

Specifies the base memory budget for internal sort operations and hash tables before writing to temporary disk files. Crucially, this is allocated per query sort/hash node, NOT per connection. Complex queries with multiple joins allocate work_mem multiple times simultaneously.

Default: 4MB
effective_cache_sizeMemory String (e.g., 24GB, 48GB)

Informs the query planner of the total memory available for disk caching (shared_buffers + kernel page cache). Does not allocate physical memory. Standard value is 75% of total system RAM on dedicated servers, or 50% on shared servers.

Default: 4GB
maintenance_work_memMemory String (e.g., 1GB, 2GB)

Specifies the maximum memory used by maintenance operations such as VACUUM, CREATE INDEX, and ALTER TABLE ADD FOREIGN KEY. Recommended ceiling is min(2GB, 5% of Total RAM); larger values accelerate index creation but autovacuum workers can exhaust host memory if unmetered.

Default: 64MB
max_connectionsInteger (10 to 5000)

Determines the maximum concurrent direct client connections. Each PostgreSQL connection spawns a distinct OS process consuming ~10MB baseline RAM plus dynamic work_mem allocations. High connection counts (>300) without PgBouncer trigger severe CPU cache thrashing.

Default: 100
checkpoint_completion_targetDecimal Float (0.1 to 1.0)

Fraction of checkpoint interval over which dirty shared buffer pages must be flushed to disk. Benchmark standard is 0.9 (90%), which smooths out write I/O spikes across the checkpoint window to eliminate I/O stutter.

Default: 0.9 (since PG 14; 0.5 in legacy versions)
wal_buffersMemory String (e.g., 16MB, 64MB)

Memory allocated for write-ahead log (WAL) data before flushing to disk. Automatically scaled to 3% of shared_buffers up to a 16MB ceiling, or 64MB for write-intensive bulk ingestion workloads.

Default: -1 (auto-tuned to 3% of shared_buffers)
random_page_costDecimal Float (1.0 to 10.0)

Planner estimate for non-sequential disk page fetches relative to sequential scans (seq_page_cost = 1.0). Set to 1.1 for NVMe SSDs and 1.5 for SATA SSDs; leaving at the 4.0 spindle HDD default causes the planner to erroneously favor sequential scans over index scans.

Default: 4.0
effective_io_concurrencyInteger (0 to 1000)

Number of concurrent asynchronous disk I/O operations the underlying storage subsystem can handle simultaneously. Optimal value is 200 to 300 for NVMe/SATA SSDs, while spinning mechanical hard drives must stay at 2.

Default: 1 (Linux default; 0 disables prefetch)
huge_pagesEnum ('on', 'off', 'try')

Controls whether shared_buffers requests Linux 2MB HugePages. Using HugePages eliminates Translation Lookaside Buffer (TLB) misses on servers with >32GB RAM, preventing page table memory bloat and reducing CPU memory access overhead by up to 15%.

Default: try

Pro Tips & Best Practices

The work_mem Multiplier Trap in Multi-Join Queries

Never calculate peak memory by simply multiplying max_connections by work_mem. A single complex SQL query with 4 hash joins, 2 sort operations, and a window function can allocate work_mem 7 times concurrently in a single backend process. If max_connections is 200 and work_mem is 64MB, worst-case memory is not 12.8GB, but over 89GB, which triggers immediate Linux OOM termination.

Why shared_buffers Above 40% Degrades Performance

PostgreSQL does not use direct I/O by default; it reads pages through the operating system kernel cache. Setting shared_buffers to 60-80% of RAM creates massive double-buffering where identical pages reside in both PostgreSQL shared buffers and Linux page cache. Leaving 50-75% of RAM free for the OS page cache allows Linux to cache index files and temporary files far more efficiently.

Locking Down Linux vm.overcommit_memory to Avoid Postmaster Termination

By default, Linux uses heuristic memory overcommit (vm.overcommit_memory = 0). When physical RAM and swap are exhausted, the Linux OOM Killer selects and terminates the process with the highest badness score, which is almost always the PostgreSQL postmaster process. In production, configure vm.overcommit_memory = 2 and vm.overcommit_ratio = 80 alongside pre-allocated HugePages to guarantee zero out-of-memory crashes.

The Connection Pooling Cliff: Why 1,000 Direct Connections Destroy Throughput

Because PostgreSQL uses a process-per-connection architecture, running 1,000 active direct connections forces the CPU to spend over 40% of its cycles on OS process context switching and L1/L2/L3 cache line invalidations. Placing PgBouncer in transaction pooling mode with pool_size = 2 * CPU_Cores + Disk_Spindles (e.g., 32-64 backend connections) increases overall query throughput by 300-500% while cutting idle memory overhead to zero.

Tuning Checkpoint Frequency to Prevent Disk Write Stalls

If PostgreSQL generates high transaction write volume, the default max_wal_size of 1GB will cause checkpoints to trigger every few seconds instead of honoring checkpoint_timeout. Increase max_wal_size to 16GB or 32GB on modern SSDs, and ensure checkpoint_completion_target is explicitly set to 0.9. This spreads disk I/O evenly across 90% of the checkpoint duration, preventing sudden disk write bottlenecks.

Common Gotchas & Troubleshooting

⚠️Out of memory: Killed process (postmaster) by Linux kernel OOM Killer

Reduce work_mem immediately or lower max_connections. Implement connection pooling (PgBouncer) so client connections do not spawn unlimited backend memory consumers. Configure vm.overcommit_memory = 2 in /etc/sysctl.conf and ensure swap space is sized to at least 50% of RAM as an emergency safety cushion.

⚠️FATAL: could not attach to shared memory segment: Cannot allocate memory

This error occurs when shared_buffers exceeds the kernel's shmmax or HugePages limits. If huge_pages = on, check 'grep Huge /proc/meminfo' to confirm HugePages_Free >= ceil(shared_buffers / 2048kB). Alternatively, set huge_pages = try, or update /etc/sysctl.conf with 'vm.nr_hugepages = [calculated_value]' followed by 'sysctl -p'.

⚠️PostgreSQL ignores indexes on SSDs and performs slow sequential table scans

The default random_page_cost is 4.0, which was calibrated for mechanical hard drives where random seeks are 4x slower than sequential reads. On NVMe and SATA SSDs, random seeks have virtually zero mechanical penalty. Set random_page_cost = 1.1 (NVMe) or 1.5 (SATA SSD) in postgresql.conf and run 'SELECT pg_reload_conf();' to instantly restore index scan priority.

⚠️Periodic query latency spikes occurring every 5 to 15 minutes

Caused by aggressive checkpoint writes flushing dirty buffers all at once. Check PostgreSQL logs for 'checkpoints are occurring too frequently'. Set checkpoint_completion_target = 0.9 to smooth out write I/O, increase max_wal_size from 1GB to 16GB+, and increase checkpoint_timeout to 15min or 30min.

⚠️High CPU utilization with hundreds of idle in transaction connections

Direct client connections consume ~10MB resident memory each even when idle, holding transaction snapshots and memory locks. Deploy PgBouncer in transaction pooling mode. Add idle_in_transaction_session_timeout = '60s' in postgresql.conf to automatically terminate orphaned client transactions.

Frequently Asked Questions

How is work_mem calculated to prevent the Linux OOM killer?▼

work_mem is calculated using the formula: work_mem = ((Total_RAM - shared_buffers) * (1 - OS_Reserve_Ratio)) / (max_connections * concurrent_sort_nodes_per_query), where OS_Reserve_Ratio is typically 0.20 (20%) and concurrent_sort_nodes is 2 for OLTP or 4 to 8 for OLAP. Because work_mem is allocated per sort/hash operation rather than per connection, keeping work_mem between 16MB and 64MB for OLTP prevents queries with multiple joins from exhausting system RAM and triggering the Linux Out-of-Memory (OOM) killer.

What is the recommended shared_buffers size for 16GB, 32GB, or 64GB RAM?▼

The recommended shared_buffers setting on Linux is 25% of total system RAM: 4GB for a 16GB server, 8GB for a 32GB server, and 16GB for a 64GB server. While PostgreSQL supports values up to 40% of RAM, setting shared_buffers higher than 40% rarely yields performance benefits and often causes severe performance degradation due to double-buffering with the operating system kernel page cache.

What is the difference between shared_buffers and effective_cache_size?▼

shared_buffers allocates real physical memory upon PostgreSQL startup to hold shared cached table and index pages. In contrast, effective_cache_size does not allocate any memory at all; it is purely an advisory metric used by the query planner to estimate how much data is likely cached in both shared_buffers and the operating system page cache combined. Standard practice is to set effective_cache_size to 50% to 75% of total host RAM.

Why does PostgreSQL crash with out of memory even when free RAM appears available?▼

PostgreSQL crashes with Out of Memory when the memory requested by backend queries exceeds the kernel's overcommit limit or when memory fragmentation prevents allocating contiguous shared memory segments. Furthermore, if Linux memory overcommit (vm.overcommit_memory = 0) is enabled, the kernel permits processes to allocate more virtual memory than physically exists; when those pages are written to, the OOM Killer abruptly executes SIGKILL on the postmaster process, crashing the database cluster.

How many max_connections should I configure for PostgreSQL?▼

Direct max_connections should ideally be restricted to 100 to 200. Because PostgreSQL uses a dedicated operating system process per connection, having more than 200 to 300 active direct connections introduces massive CPU context switching and lock contention. For applications requiring hundreds or thousands of concurrent client connections, use a connection pooler like PgBouncer in transaction mode with pool_size set to (2 * CPU_Cores + Spindle_Count), allowing thousands of client sessions to share 20 to 50 active database backends.

Should I enable HugePages on Linux for PostgreSQL?▼

Yes, HugePages should always be enabled for production databases with 32GB of RAM or more. Standard x86_64 Linux memory pages are 4KB, requiring millions of page table entries for large shared_buffers, which bloats CPU memory consumption and causes Translation Lookaside Buffer (TLB) misses. Linux 2MB HugePages reduce page table overhead by a factor of 512, delivering 5% to 15% higher query throughput and eliminating shared memory allocation crashes.

What random_page_cost should I use for NVMe and SSD storage?▼

Set random_page_cost to 1.1 for NVMe SSDs and 1.5 for SATA SSDs, compared to the baseline seq_page_cost of 1.0. The default value of 4.0 was established decades ago for spinning magnetic hard drives that suffered significant mechanical seek latency. Retaining 4.0 on SSD storage causes the PostgreSQL query planner to overestimate the cost of index lookups and erroneously execute full table sequential scans.

What is the difference between maintenance_work_mem and autovacuum_work_mem?▼

maintenance_work_mem dictates the memory allocated for manual administrative tasks like CREATE INDEX and VACUUM FULL, typically set between 1GB and 2GB. autovacuum_work_mem specifically limits the memory allocated to each background autovacuum worker process. If autovacuum_work_mem is left at -1, each worker uses maintenance_work_mem; with autovacuum_max_workers = 3, three concurrent workers could consume 6GB of RAM, risking system exhaustion. Setting autovacuum_work_mem explicitly (e.g., 512MB) insulates normal query operations.

Related Tools & Utilities

All Tools →