Short title

Standard Deviation & Variance Calculator

Calculate sample and population standard deviation, variance, mean, and margin of error instantly. Clean messy datasets with outlier detection and normal curve.

Presets:
Lbl control deck
30 Lbl valid points
30 Lbl valid points
Lbl regime
Lbl confidence level
Lbl outlier treatment
Lbl tukey multiplier1.5x IQR
Lbl tukey sensitiveLbl tukey standardLbl tukey extreme
Lbl bessel card title

Lbl bessel note

Lbl living health insight

Lbl sample std devn - 1
7.9997
Lbl sample variance: 63.9954
Lbl pop std devN
7.8653
Lbl pop variance: 61.8622
Lbl meanΣx / n
82.9333
Lbl sum: 2,488 (n = 30)
Lbl std error1.4605
Lbl coeff var9.65%
Lbl median83.5
Lbl i q r12
Lbl confidence interval (95%)x̄ ± 2.9868 (t* = 2.045)
[79.9465to85.9201]
Lbl skewness-0.21Approximately Symmetrical
Lbl kurtosis-0.906Platykurtic (Light tails)
Lbl count30
Lbl mean82.9333
Lbl sample std dev7.9997
Lbl std error1.4605
Lbl median83.5
Lbl margin of error±2.9868
Technical Reference & Architecture Guide

Standard Deviation & Variance Calculator Guide

Calculate sample and population standard deviation, variance, mean, and margin of error instantly. Clean messy datasets with outlier detection and normal curve.

Standard Deviation & Variance Calculator Guide — Client-Side In-Memory Architecture & Data Flow

Key Parameters & Controls

Sample Standard Deviation (s)Statistical Dispersion Estimator

Measures variability around the sample average using Bessel's correction (dividing by n - 1). This adjustment prevents underestimating real-world spread when analyzing sample subsets, such as a runner's weekly 5K split times, a student's semester exam marks, or monthly family grocery spending.

Default: Unbiased (n - 1) degrees of freedom
Population Standard Deviation (σ)Parametric Dispersion Constant

Quantifies the true spread of an entire closed group by dividing total squared deviations by N. Strictly valid only when every single entity in the defined universe is measured without estimation, such as all 30 students in a specific classroom, all 12 electric bills in a calendar year, or every heartbeat logged during a finished race.

Default: True parameter (N degrees of freedom)
Sample Variance (s²)Mean Squared Deviation Metric

The average squared distance of each observation from the arithmetic mean, expressed in squared units (such as seconds² or points²). While less intuitive for daily pacing or budgeting than standard deviation, variance serves as the fundamental additive engine for comparing group consistency in athletic training and academic performance.

Default: Sum of squared deviations / (n - 1)
Standard Error of the Mean (SE)Sampling Precision Indicator

Measures how accurately your sample average represents the true population mean, calculated as s / √n. While standard deviation reflects natural spread among individual data points (such as daily resting heart rates), standard error reflects confidence in your overall average, shrinking as you log more workouts or health trials.

Default: s / √n precision index
Coefficient of Variation (CV)Normalized Relative Dispersion

The ratio of standard deviation to the mean expressed as a percentage: (s / Mean) × 100%. Provides a scale-free benchmark to compare consistency across vastly different magnitudes, such as comparing heart rate variability during deep sleep (mean 60 bpm, s = 3 bpm, CV = 5%) versus high-intensity interval sprints (mean 170 bpm, s = 8.5 bpm, CV = 5%).

Default: Percentage volatility ratio ((s / Mean) × 100%)
Interquartile Range (IQR)Non-Parametric Spread Measure

The spread between the 75th percentile (Q3) and 25th percentile (Q1), defining the central 50% core of your data. Because IQR resists extreme distortions from one-off GPS glitches, accidental misreadings, or holiday spending spikes, it serves as the clinical and athletic benchmark for identifying true anomalies via Tukey's 1.5 × IQR fences.

Default: Q3 - Q1 middle 50% range
Pro Tips & Best Practices

Catastrophic Cancellation in Simplified Formulas

Avoid using the simplified shortcut formula (Sum of x² - (Sum of x)² / n) when evaluating numbers with high base values and narrow spreads, such as GPS elevation benchmarks (1,842.1 m, 1,842.3 m) or marathon chip timestamps. Subtracting two massive, nearly identical calculated totals causes catastrophic loss of decimal precision. Always calculate the true sample mean first, determine each individual point's deviation, and then square those differences.

The Empirical Rule Fallacy on Skewed Data

The classic 68-95-99.7% Empirical Rule strictly assumes a symmetrical, bell-shaped Gaussian distribution. When tracking naturally skewed real-life metrics—such as household net savings, recovery hours between marathon training blocks, or daily driving commute delays—the distribution clusters toward a hard physical minimum of zero. Applying ±2 standard deviations to skewed data predicts impossible negative boundaries; rely instead on the median and Interquartile Range (IQR).

Sample Standard Deviation Remains Slightly Underestimated in Small Batches

While Bessel's correction (dividing by n - 1) makes sample variance (s²) mathematically unbiased, the square root operation reintroduces a subtle downward bias in sample standard deviation (s) due to Jensen's inequality. When working with small sample sizes under 10 observations—such as timing 5 sprint repetitions or logging 7 consecutive resting blood pressure mornings—the calculated standard deviation will typically underestimate true dispersion by 3% to 6%.

The Law of Diminishing Returns in Sample Size Precision

Because standard error contracts with the square root of your sample size (√n), halving your margin of error requires quadrupling your observations. Increasing your tracked running sessions or fuel economy logs from 10 to 40 entries cuts estimation uncertainty by 50%, but advancing from 40 to 70 entries yields only an incremental 18% improvement. Focus on consistent, high-fidelity data collection rather than obsessing over sample volume.

Common Gotchas & Troubleshooting

⚠️Sample Standard Deviation Returns Undefined or Division by Zero

Sample standard deviation requires at least two distinct data points (n ≥ 2) because Bessel's correction divides by (n - 1). When only a single observation is entered (n = 1), degrees of freedom equal zero, making variance mathematically indeterminate. Switch to Population Mode if analyzing an isolated, complete single event (where N = 1, σ = 0), or input additional sample observations.

⚠️Standard Deviation Evaluates to Exactly Zero (s = 0)

A standard deviation of exactly zero indicates that every single entered value is identical (e.g. four consecutive lap times of exactly 62.0 seconds). While mathematically valid, zero dispersion signifies absolute consistency and will trigger division-by-zero errors in downstream normalized formulas such as the Coefficient of Variation and standard Z-scores.

⚠️Legitimate Peak Performances Flagged as False Outliers

Standard outlier filters flag any point falling beyond 1.5 × IQR as an anomaly, which assumes a balanced bell curve. In real-world fitness and personal activity—such as an intentional interval sprint pace spike or an annual holiday heating bill—heavy-tailed peaks are natural. Increase your outlier threshold to 3.0 × IQR (extreme outer fences) or corroborate entries against your training logs before discarding valid data.

⚠️Confidence Interval Lower Bound Dips Below Physical Zero Limits

Symmetrical confidence intervals (Mean ± Margin of Error) assume that variation spreads equally above and below the average. When the average is small and relative variance is high—such as counting weekly missed workouts or vehicle maintenance incidents—the lower limit can mathematically dip into negative territory. Clamp the lower bound at zero or report non-parametric median and percentile intervals for non-negative physical metrics.

Frequently Asked Questions

How do you calculate standard deviation step by step?▼

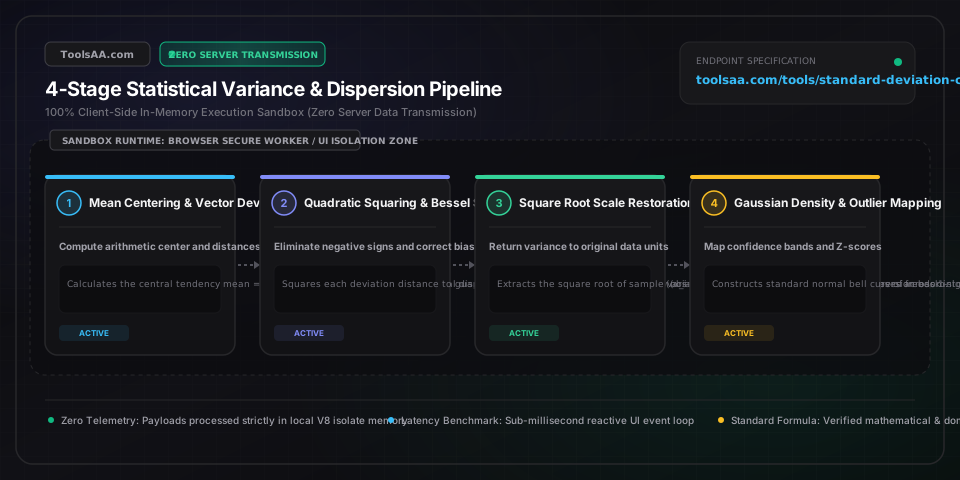
To calculate sample standard deviation, calculate the arithmetic mean, subtract the mean from each data point, square each individual difference, sum all squared differences, divide that total sum by n - 1 (Bessel's correction), and take the positive square root: s = √[ Σ(x - Mean)² / (n - 1) ]. For example, with numbers 4, 8, and 12, the mean is 8; squared differences from 8 are 16, 0, and 16 (summing to 32); dividing by (3 - 1 = 2) yields a variance of 16, resulting in a standard deviation of 4.

What is considered a good or normal standard deviation?▼

A good standard deviation is relative to the scale of your mean, quantified by the Coefficient of Variation (CV = s / Mean × 100%). In athletic pacing and resting biometrics, a CV under 5% to 8% represents elite consistency, while 10% to 15% is standard for recreational runners and daily fitness tracking. In precision manufacturing and medical dosing, a CV below 1% to 2% is mandatory, whereas volatile financial assets frequently exhibit standard deviations exceeding 30% of their mean.

What is the difference between standard deviation and variance?▼

Variance measures average dispersion in squared units (such as seconds² or dollars²), whereas standard deviation is the square root of variance, expressing spread in the exact original units of your data (such as seconds or dollars). While variance is mathematically foundational for ANOVA tests and statistical modeling, standard deviation provides an intuitive, real-world metric of spread directly comparable to your daily measurements.

What is the difference between standard deviation and standard error?▼

Standard deviation measures the natural variability of individual observations within a dataset, whereas standard error of the mean (SE = s / √n) measures how closely your sample average reflects the true population mean. Standard deviation describes data spread and remains relatively stable as sample size grows, whereas standard error reflects estimation precision and continuously decreases toward zero as you collect more observations.

Why do you divide by n minus 1 instead of n for sample standard deviation?▼

You divide by n - 1 (known as Bessel's correction) because sample observations naturally cluster closer to their own sample mean than to the true overall population average. Calculating the sample mean from the data introduces an algebraic constraint (all deviations sum to zero), consuming one degree of freedom. Dividing by n systematically underestimates true population dispersion; dividing by n - 1 mathematically corrects this bias to provide an accurate, unbiased estimate.

Related Tools & Utilities

All Tools →