/
P Value Calculator & Hypothesis Test Solver

P Value Calculator & Hypothesis Test Solver

Badge tier

P value calculator to calculate p-values for Z, t, chi-square, and F tests. Find one-tailed and two-tailed significance, critical values, and reverse test goals.

Lbl quick presets
Lbl regime title
2.450
58
0.05
Lbl multi compLbl bonferroni adj 0.05000
Lbl verdict headingLbl reject h0
Badge sig evidence
Lbl p value exact0.01731.73e-2
Lbl test stat score2.450T (58 df)
Lbl crit boundary2.002α = 0.0500
Lbl nominal alpha0.05k = 1

Heading explanation

Exp significant text

Lbl ci95[0.490, 4.410]

Hint ci

Lbl test directionLbl bilateral

Hint tail

Lbl scrubber2.45

Disclaimer title Disclaimer text

Footer stat1 titleFooter stat1 value
Footer stat2 titleFooter stat2 value
Footer stat3 titleFooter stat3 value

Client-Side Processing

High-performance calculation executed entirely in browser memory.

Zero Server Upload Privacy

All payloads remain strictly local with zero external server communication.

Production Ready Export

Clean, optimized output formats ready for immediate deployment.

Technical Reference & Architecture Guide

P Value Calculator & Hypothesis Test Solver Guide

P value calculator to calculate p-values for Z, t, chi-square, and F tests. Find one-tailed and two-tailed significance, critical values, and reverse test goals.

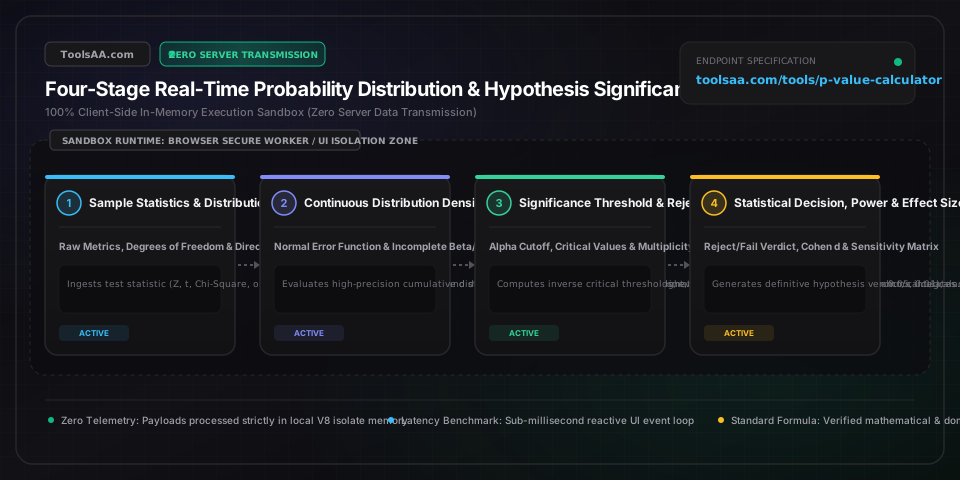
P Value Calculator & Hypothesis Test Solver Guide — Client-Side In-Memory Architecture & Data Flow

Key Parameters & Controls

Standardized Test Statistic (Z, t, Chi-Square, or F Score)standardized discrepancy score (real dimensionless float)

Normalized measure of deviation between sample data and the null hypothesis H0. Follows a standard normal distribution N(0,1) for large-sample Z-tests, Student t for unknown population variance with df = n-1, Pearson chi-square sum for contingency/goodness-of-fit tables, or variance ratio for F-tests.

Default: 2.450 (Standard Deviation Metric / t-Score)
Degrees of Freedom (df / df1 & df2)discrete parameter constraint (positive integer >= 1)

Number of independent values or observations free to vary in statistical calculation. For single-sample or paired t-tests, df = n - 1; for two-sample pooled t-tests, df = n1 + n2 - 2; for contingency tables, df = (rows - 1)(cols - 1); for ANOVA, between-group df1 = k - 1 and within-group df2 = N - k.

Default: 28 (Sample Size n = 29 Single-Sample Baseline)
Significance Threshold Alpha (α)Type I error probability limit (ratio 0.0001 - 0.2000)

Maximum acceptable probability of committing a Type I error (falsely rejecting a true null hypothesis). Canonical scientific conventions mandate α = 0.05 (5% false positive risk, 95% confidence), α = 0.01 in medical/pharmaceutical trials, or α = 0.001 for high-stakes genomic and engineering discovery.

Default: 0.050 (Standard 95% Confidence Threshold)
Hypothesis Directionality (One-Tailed vs Two-Tailed)directional alternative hypothesis enum (Left, Right, Two-Sided)

Determines probability distribution tail coverage. Two-tailed tests (H1: μ ≠ μ0) evaluate deviation in either direction, allocating α/2 to each tail. One-tailed tests (Left: H1: μ < μ0, Right: H1: μ > μ0) place the entire α rejection region in one tail, providing higher statistical power but blind to reverse effects.

Default: Two-Tailed (Bilateral Standard H1: μ ≠ μ0)
Calculated P-Value (p)tail probability density integral (ratio 0.00000 to 1.00000)

Exact probability under the null hypothesis of obtaining a test statistic at least as extreme as the observed sample value: p = P(T >= |t_obs| | H0) * 2 for two-tailed tests. If p < α, data provides sufficient evidence to reject H0; if p >= α, researchers fail to reject H0.

Default: 0.0184 (Statistically Significant at α = 0.05)
Standardized Effect Size (Cohen d / Pearson r / Eta-Squared)practical magnitude metric (standardized mean difference)

Measures the absolute magnitude of an experimental effect independent of sample size: Cohen d = (mean1 - mean2) / s_pooled. Standard benchmark thresholds: d = 0.20 (small), d = 0.50 (medium), d = 0.80 (large). Prevents conflating small p-values derived from massive N with real-world practical significance.

Default: 0.650 (Medium-to-Large Practical Impact)
Pro Tips & Best Practices

Never Confuse Statistical Significance (p < .05) with Practical Effect Size

With large sample sizes (e.g. N = 100,000 in e-commerce A/B tests), even microscopic, economically irrelevant differences like a 0.001% conversion shift produce p < 0.0001. A tiny p-value proves only that the observed difference is unlikely due to random sampling noise, not that the magnitude is meaningful. Always report Cohen d, Relative Risk, or raw metric confidence intervals alongside the p-value.

Pre-Specify Directionality Before Testing to Prevent One-Tailed p-Hacking

Switching from a two-tailed to a one-tailed test after inspecting data cuts your p-value exactly in half (e.g., p = 0.08 becomes p = 0.04), artificially pushing marginal results into 'statistical significance'. Regulators like the FDA and peer-reviewed journals mandate that directional one-tailed hypotheses must be registered in advance with strict biological or physical justification.

Apply Bonferroni or FDR Corrections When Evaluating Multiple Hypothesis Endpoints

When running multiple statistical tests simultaneously (e.g., testing 20 metrics in an A/B test or 1,000 gene variants in GWAS), the family-wise error rate escalates according to FWER = 1 - (1 - alpha)^k. At k = 20 tests with alpha = 0.05, you have a 64.2% chance of finding at least one false positive. Divide your significance threshold by the number of comparisons (Bonferroni: alpha_adj = 0.05 / 20 = 0.0025) or use the Benjamini-Hochberg False Discovery Rate procedure.

Prefer Welch t-Test Over Student t-Test to Guard Against Heteroscedasticity

Student classic two-sample t-test assumes equal population variances (homoscedasticity). If sample sizes are unequal (e.g., n1 = 100, n2 = 30) and variances differ by more than a 2:1 ratio, Student t can inflate Type I error rates up to 15% or crush statistical power. Welch t-test with Satterthwaite degrees of freedom automatically adjusts for unequal variances with zero power penalty when variances are equal.

Common Gotchas & Troubleshooting

⚠️Calculated p-value displays as 0.0000 or p < 0.0001 instead of an exact decimal

When extreme test statistics are observed (such as Z > 4.5 or t > 5.0 with large df), the tail probability drops below 0.00001 (less than 1 in 100,000). APA style guidelines mandate reporting these extreme values as 'p < .001' or using scientific notation (e.g., 2.34e-6) rather than rounding down to absolute zero, since theoretical probability tails in normal and t-distributions asymptotically approach but never strictly equal zero.

⚠️One-tailed p-value is greater than 0.500 despite a high absolute test statistic

This occurs when your sample effect is in the direction opposite to your directional alternative hypothesis (for example, testing H1: μ > 0 with an observed negative test statistic Z = -2.10). The right-tailed probability is 1 - P(Z < -2.10) = 0.9821. If your experimental result contradicted your predicted direction, the null hypothesis cannot be rejected; do not flip the sign post-hoc to rescue significance.

⚠️Chi-Square or F-test p-value shows an unexpected tail option

Unlike the symmetric normal and Student t distributions which support left-, right-, and two-tailed evaluations, the Chi-Square goodness-of-fit/contingency test and Fisher ANOVA F-test are fundamentally omnibus right-tailed tests. Because squared deviations and variance ratios are bounded strictly at zero, extreme test statistics always fall in the positive upper right tail. Two-tailed options are mathematically invalid for standard chi-square and ANOVA tests.

⚠️Discrepancy between two-sample t-test p-value and regression slope p-value

In simple linear regression with a binary treatment dummy variable, the t-statistic on the treatment slope coefficient matches the two-sample pooled Student t-test exactly: t^2 = F. If you observe a minor discrepancy, verify whether your t-test used Welch correction (unequal variance) while the standard OLS regression assumed homoscedastic residual variance, or whether robust standard errors (HC1/HC3) were applied.

Frequently Asked Questions

How do you calculate a p-value from a Z-score or t-score?▼

To calculate a p-value, integrate the probability density function of the test distribution from the observed test statistic to infinity. For a standard normal distribution, compute the cumulative distribution function Φ(z): for a two-tailed test, p = 2 * (1 - Φ(|z|)). For example, with Z = 1.96, Φ(1.96) = 0.9750, giving p = 2 * (1 - 0.9750) = 0.0500. For a Student t-distribution with degrees of freedom df, evaluate the regularized incomplete beta function: p = I_{df/(df + t^2)}(df/2, 1/2).

What is a good p-value for statistical significance?▼

A p-value below 0.05 (p < .05) is the conventional gold standard for statistical significance across scientific research, indicating less than a 5% probability that observed differences occurred under the null hypothesis. However, specific fields mandate stricter standards: peer-reviewed clinical trials frequently require p < 0.01 or p < 0.001 with multiplicity adjustments, genome-wide association studies (GWAS) enforce p < 5 × 10^-8 to prevent millions of false positives, and particle physics requires 5-sigma (p < 3 × 10^-7) for confirmed discovery.

What is the difference between a one-tailed and two-tailed p-value?▼

A two-tailed p-value tests whether an effect exists in either direction (positive or negative, H1: μ ≠ μ0) by splitting the alpha significance threshold equally between both distribution tails (α/2 = 0.025 each). A one-tailed p-value tests directionality in a single pre-specified direction (H1: μ > μ0 or H1: μ < μ0), concentrating the entire alpha threshold (α = 0.05) in one tail. For symmetric Z and t distributions with identical test statistics, the two-tailed p-value is exactly double the one-tailed p-value.

Does a high p-value mean the null hypothesis is true?▼

No, a high p-value (p ≥ 0.05) does not prove that the null hypothesis is true; it merely indicates that the observed sample data does not provide sufficient evidence to reject it (absence of evidence is not evidence of absence). A high p-value often stems from inadequate statistical power or small sample sizes (Type II error), where a true meaningful treatment effect exists in the population but the study lacked sufficient sample size N to detect it statistically.

How do you find the critical value from an alpha level?▼

To find the critical value from an alpha level, evaluate the inverse cumulative distribution function (quantile function) for the chosen distribution and degrees of freedom. For a standard normal distribution at two-tailed α = 0.05, calculate the 1 - (α / 2) = 0.975 quantile: Z* = Φ^-1(0.975) = 1.95996 (rounded to 1.96). For a Student t-distribution with df = 20 at two-tailed α = 0.05, t* = t^-1(0.975, 20) = 2.086. Any observed test statistic exceeding this critical threshold yields p < α.

What is the relationship between p-values and 95% confidence intervals?▼

A two-tailed hypothesis test at significance level α = 0.05 is mathematically equivalent to checking whether the hypothesized null value falls within the 95% confidence interval (CI = 1 - α). If the 95% confidence interval for a treatment difference [0.42, 3.18] does not include zero (the null value), the two-tailed p-value is guaranteed to be less than 0.05. Conversely, if the 95% confidence interval overlaps zero (e.g., [-0.35, 2.10]), the p-value is guaranteed to be greater than or equal to 0.05.

Related Tools & Utilities

All Tools →