Nav title
Badge tier

Text Deduplicator & Remove Duplicate Lines

Text deduplicator to remove duplicate lines from lists. Trim whitespace, ignore case, isolate unique rows, and export clean data instantly in your browser.

Badge private
Zero server
Presets
Lbl input title0 Lbl lines
Lbl strategy
Lbl delimiter
Lbl pipeline ingest44.4% Stat reduction rate
Lbl pipeline ingestNFCLbl pipeline normalizeO(N)Lbl pipeline engineFLTRLbl pipeline strategyLbl pipeline output
0 Lbl lines•218 Lbl characters•Lbl format: CRLF
Local Sandbox Only
Lbl join delimiter
0 Lbl lines•-0 Stat duplicate count•44.4% Stat reduction rate
Stat bytes saved: 0 Lbl bytes
Stat original count0
Stat unique count0 (55.6%)
Stat duplicate count0 (44.4%)

Client-Side Processing

High-performance calculation executed entirely in browser memory.

Zero Server Upload Privacy

All payloads remain strictly local with zero external server communication.

Production Ready Export

Clean, optimized output formats ready for immediate deployment.
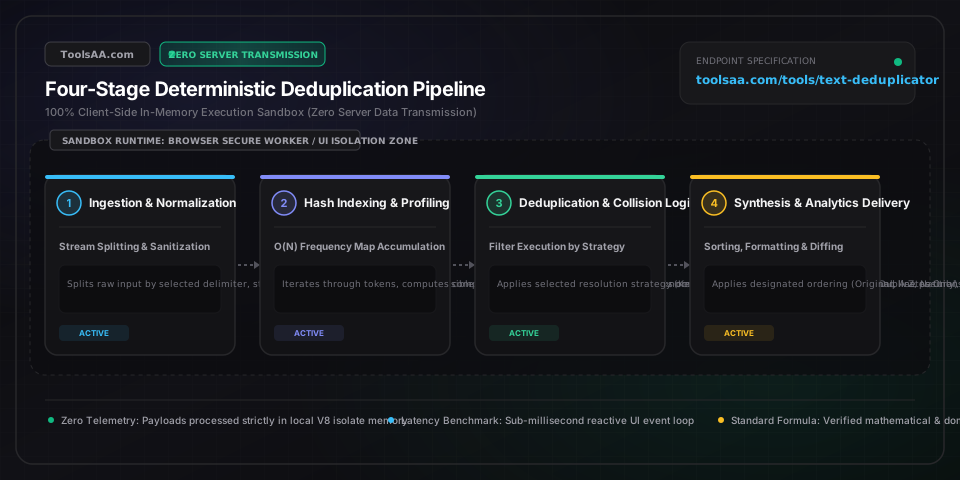
Technical Reference & Architecture Guide

Text Deduplicator & Remove Duplicate Lines Guide

Text deduplicator to remove duplicate lines from lists. Trim whitespace, ignore case, isolate unique rows, and export clean data instantly in your browser.

Text Deduplicator & Remove Duplicate Lines Guide — Client-Side In-Memory Architecture & Data Flow

Key Parameters & Controls

Deduplication Strategy ModeCollision Resolution Strategy

Determines disposition when recurring tokens collide. 'Keep First' preserves original entry sequence for append-only audit trails. 'Keep Last' captures newest state transitions in time-series logs. 'Singletons Only' excludes any element occurring 2 or more times to isolate non-duplicated outliers. 'Duplicates Only' isolates exclusively lines with frequency >= 2 for collision auditing.

Default: Keep First Occurrence
Unicode Normalization & Case FoldingText Normalization Standard

Applies Unicode Canonical Decomposition followed by Canonical Composition (NFC per Unicode Standard Annex #15) alongside full case folding (RFC 3454). Distinguishes precomposed characters from combining character sequences and standardizes locale-independent casing (such as German 'ß' to 'ss' or Greek sigma 'ς'/'σ'/'Σ'), preventing false-negative duplicate detection across heterogeneous systems.

Default: Case-Insensitive (NFC Folded)
Whitespace & Line-Break SanitizationSanitization Filter

Normalizes cross-platform newline discrepancies (Windows CRLF 0x0D 0x0A, Unix LF 0x0A, legacy Mac CR 0x0D). Eliminates leading and trailing ASCII whitespace (0x20) and tab stops (0x09), while filtering non-breaking spaces (U+00A0) and zero-width spaces (U+200B). Prevents identical visible text from failing duplicate checks due to invisible trailing carriage returns.

Default: Trim Leading/Trailing Whitespace
Sequence Sorting & Lexicographical OrderingOrder Disposition

Specifies post-deduplication ordering. 'Preserve Input Order' maintains initial occurrence chronology with O(N) lookup. 'Natural Alphanumeric' implements chunk-based numerical sorting (e.g. 'item_2' before 'item_10' rather than standard ASCII 0x31 sorting). 'Frequency Count Descending' ranks tokens by occurrence density for Pareto distribution analysis.

Default: Preserve Input Order
Delimiter & Token Boundary ParserTokenization Grammar

Configures stream segmentation boundaries. Standard newline splits lines, while CSV/TSV delimiters allow comma (,) or tab (\t) column extraction. Custom regular expressions allow arbitrary multi-character delimiter matching without requiring manual find-and-replace pre-processing.

Default: Universal Line Breaks (\r?\n)

Pro Tips & Best Practices

Beware Invisible Windows CRLF Trailing Byte Drag in Web Pastes

When copying text from Windows Excel or Notepad into a browser, lines frequently terminate with carriage return \r characters. If one line has \r\n and an identical-looking line copied from a web browser has only \n, strict byte comparisons evaluate them as distinct strings. Always enable 'Trim Whitespace' to strip trailing \r bytes before duplicate indexing.

The Hidden Zero-Width Space Pitfall in Web Scrapes (U+200B & U+00A0)

Scraped text and rich-text editors often contain non-breaking spaces (ASCII 160 / Unicode U+00A0) or zero-width spaces (U+200B). Standard string trimming in many naive scripts only removes standard ASCII space (0x20). Ensure advanced Unicode whitespace normalization is active when deduplicating text extracted from modern web pages, Google Sheets, or CMS databases.

Deterministic Deduplication Requires Casing Invariance Before Case Recovery

If you have 'Apple' at line 1 and 'apple' at line 50, a case-insensitive deduplication in 'Keep First' mode must retain 'Apple', whereas 'Keep Last' must retain 'apple'. The algorithm maps lowercase tokens in a lookup index while storing the reference to the original case, ensuring output retains authentic styling rather than converting your entire document into lowercase.

Pareto Distribution in Large Text Lists (The 80/20 Duplicate Skew)

In email lists, server logs, and search keyword dumps, roughly 20% of unique tokens account for 80% of duplicate occurrences. Sorting by 'Frequency Descending' immediately surfaces anomalous bot spam (e.g. single IP repeating 10,000 times) or bulk subscriber scraping without having to export data into external spreadsheet pivot tables.

Common Gotchas & Troubleshooting

⚠️Identical-looking text lines fail to deduplicate and remain duplicated in the output

Check for trailing spaces, invisible carriage return \r characters from Windows/Excel sources, or non-breaking spaces (U+00A0). Activate both 'Trim Whitespace' and 'Unicode Normalization' to sanitize invisible character padding.

⚠️Case-insensitive deduplication unexpectedly modifies the casing of single items

Ensure your deduplication strategy is set to 'Keep First Occurrence' rather than a force-lowercase export. The engine indexes tokens using lowercase hash keys while preserving the original casing of the first-encountered instance.

⚠️Alphanumeric IDs with numbers sort incorrectly (e.g., ID-10 appears before ID-2)

Standard lexicographical sorting compares character codes sequentially ('1' < '2'), placing '10' before '2'. Switch the sort order parameter to 'Natural Alphanumeric Sort' to parse contiguous integer fragments numerically.

⚠️Browser UI becomes sluggish when pasting text files exceeding 100,000 lines

Disable side-by-side 'Diff Inspector' for massive datasets exceeding 50,000 lines. The core deduplication algorithm operates in O(N) linear time with Hash Maps, but complex DOM visual diff rendering incurs memory overhead. Use the direct 'Cleaned Output' tab for instant processing.

Frequently Asked Questions

How to remove duplicate lines from a text file while preserving original order?▼

To remove duplicate lines while preserving original order, iterate through the line array sequentially using a Hash Set to track seen items in O(N) time complexity. Only output a line if its normalized key has not yet been added to the Set, adding the key upon first encounter. This retains the exact chronological sequence of first appearances, unlike Unix sort -u which sorts lines alphabetically.

What is the difference between removing duplicates and finding unique lines?▼

Removing duplicates reduces repeated occurrences to a single representative entry (e.g. [A, B, A, C] becomes [A, B, C]). Finding unique lines (also called singletons or distinct non-repeated values) completely discards any line that appeared more than once, returning only items that occurred exactly once (e.g. [A, B, A, C] returns only [B, C]).

How does case-sensitive vs case-insensitive deduplication handle Unicode text?▼

Case-sensitive deduplication performs strict UTF-16 code unit matching, treating 'Tokyo' and 'tokyo' as completely distinct items. Case-insensitive deduplication applies Unicode full case folding (such as transforming German 'ß' to 'ss' and standardizing accented characters), mapping uppercase and lowercase variations to a canonical comparison key while keeping the original casing of the first encountered entry.

How to remove duplicate lines across large CSV or tab-delimited spreadsheets?▼

Set the delimiter to universal line breaks (\n) to deduplicate full spreadsheet rows, or choose comma (,) or tab (\t) to extract unique single-column entries. Pre-filtering by trimming whitespace and stripping blank rows ensures entries exported from Microsoft Excel or Google Sheets containing stray spaces or Windows carriage returns (\r\n) are deduplicated accurately.

Related Tools & Utilities

All Tools →